

Democratizing Agentic Access to Bioinformatics and Biopharmaceutical Databases and Analyses with BioMCP-TS. Part of the BioResearcher Agent Suite.
- ✓Open-source license (Apache-2.0)
- ✓Actively maintained (<30d)
- ✓Clear description
- ✓Topics declared
- ✓Documented (README)
- !README contains suspicious pattern: eval\s*\(
claude mcp add biomcp-ts -- npx -y biomcp{
"mcpServers": {
"biomcp-ts": {
"command": "npx",
"args": ["-y", "biomcp"]
}
}
}Resumen de MCP Servers
# BioMCP [](https://www.npmjs.com/package/biomcp) [](https://www.npmjs.com/package/biomcp) [](https://www.npmjs.com/package/biomcp) [](https://github.com/yeyuan98/biomcp-ts/commits/main) [](https://doi.org/10.5281/zenodo.22178957) 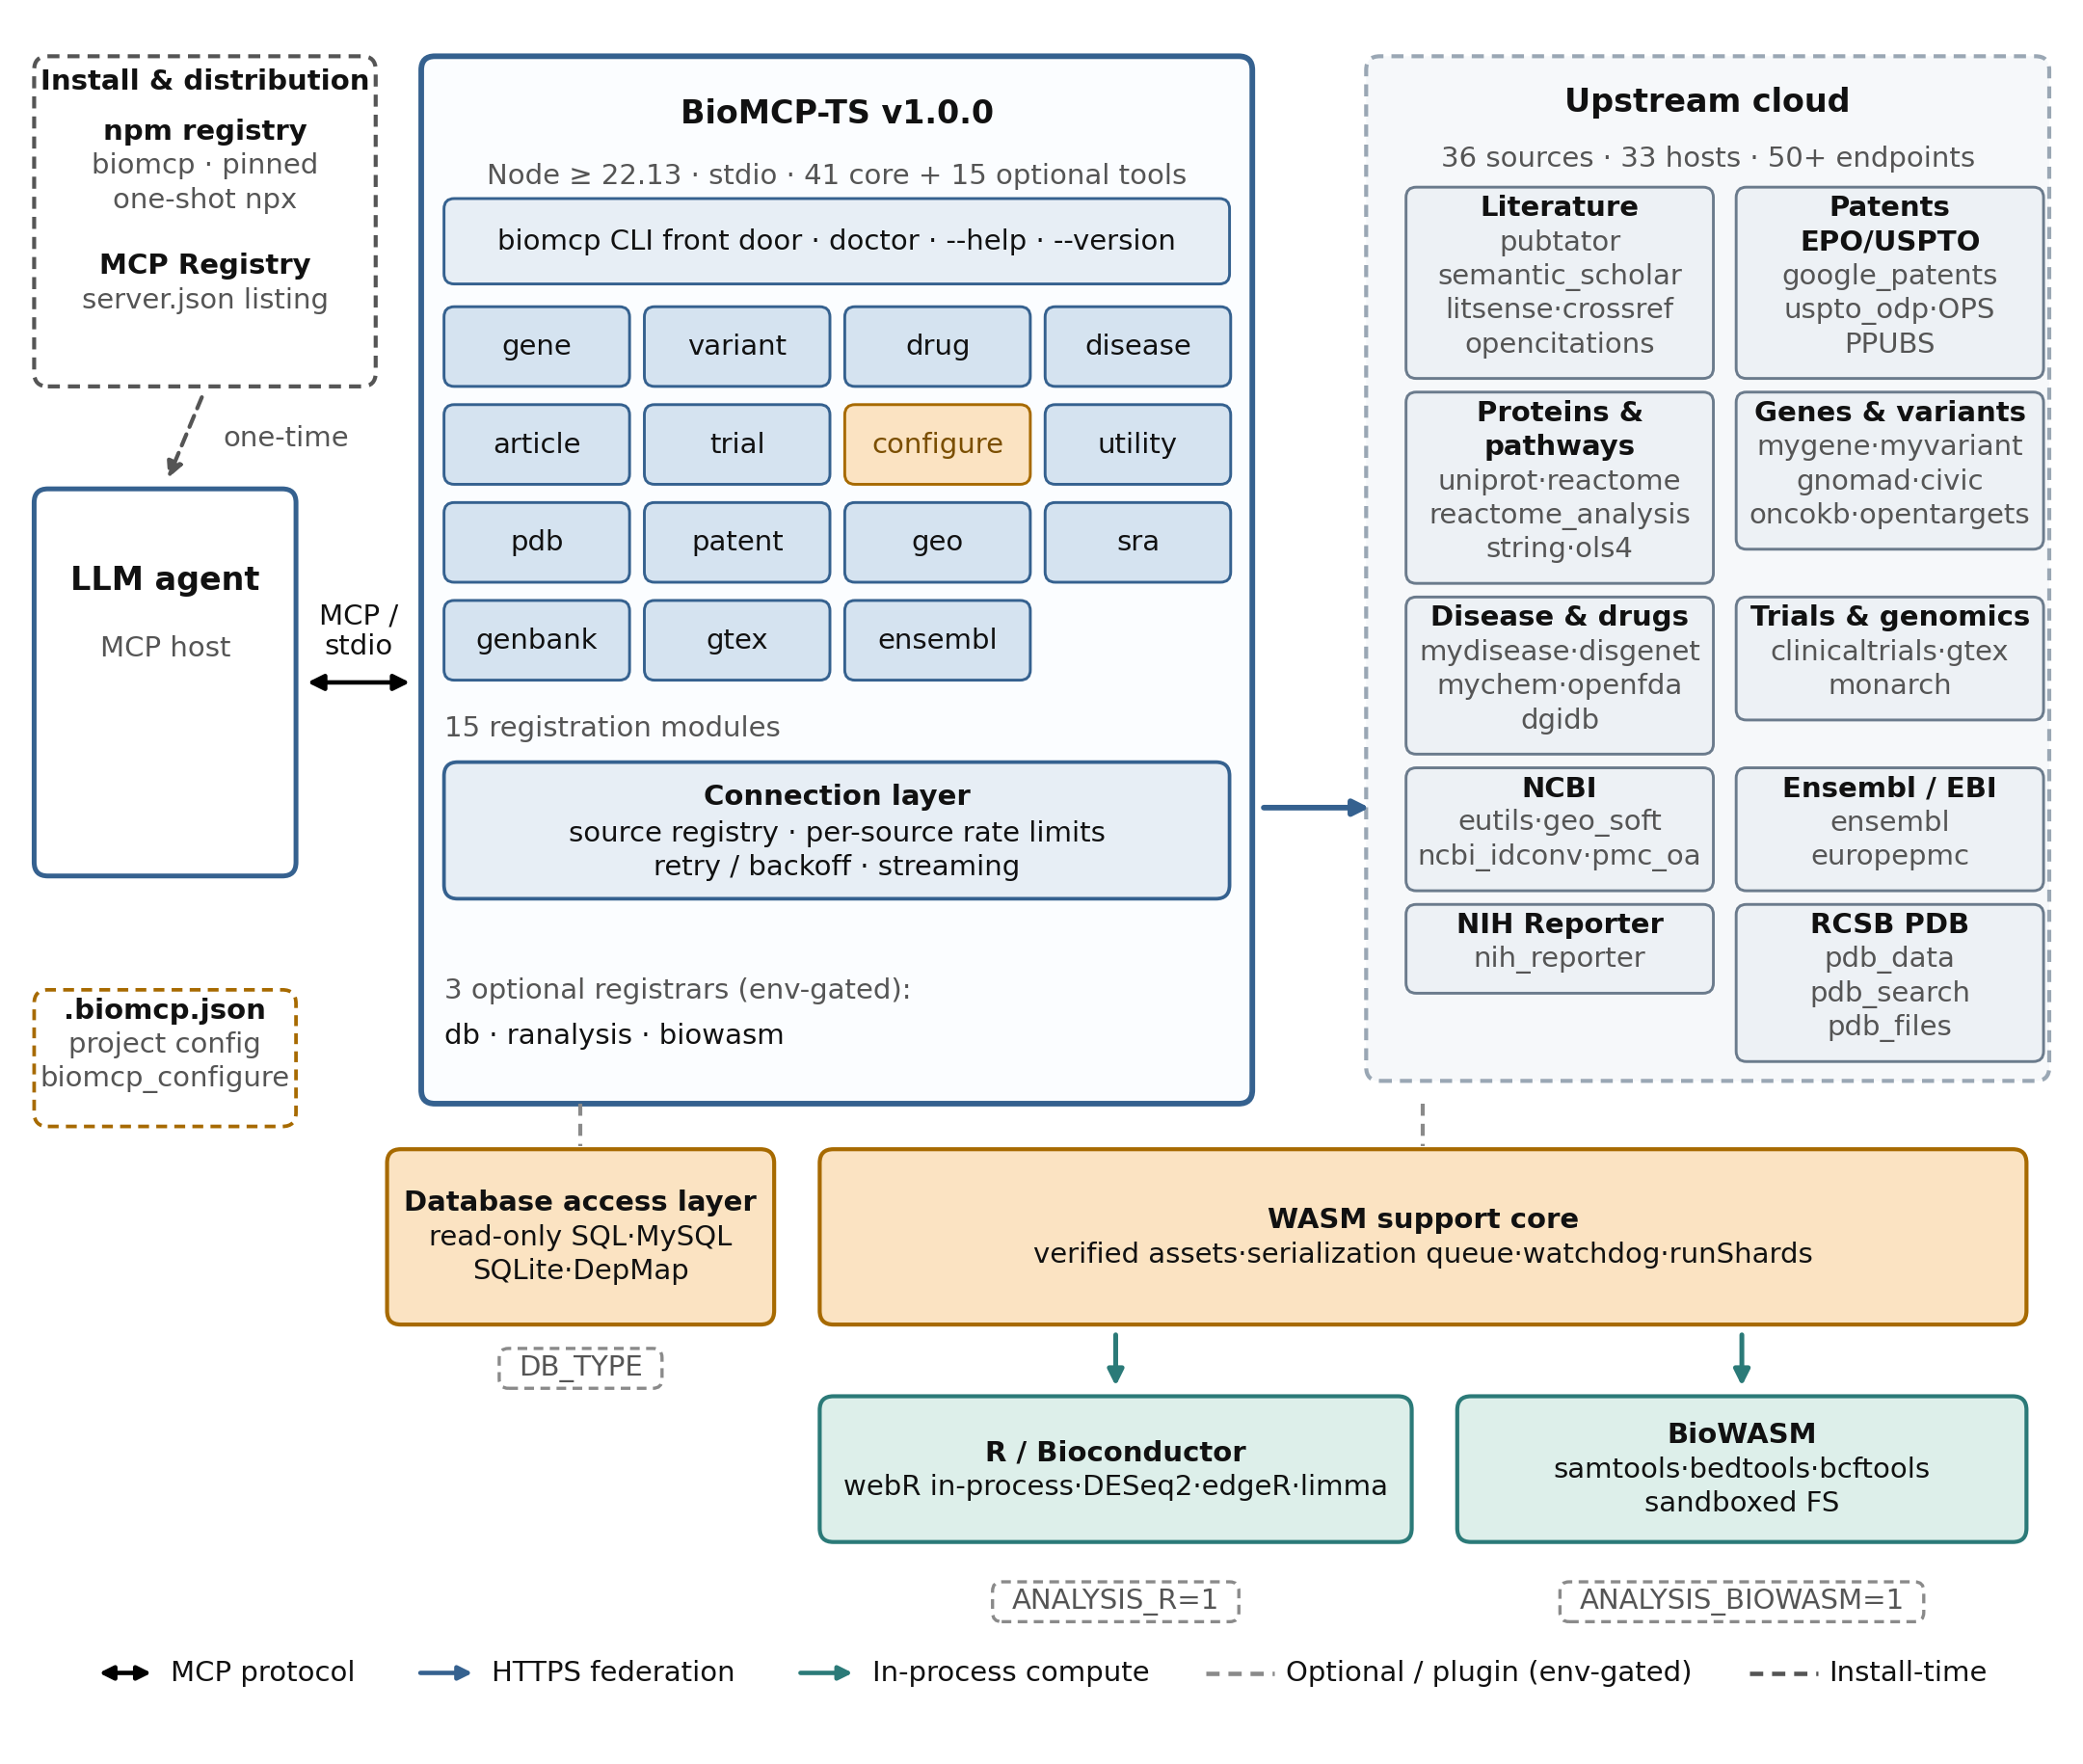 ## Highlights **Democratizing agentic access to bioinformatics and biopharmaceutical databases and analyses.** - Section-based federated access to 50+ bioinformatics, pharmaceutical, and patent databases - Optional toolboxes for local database curation and dependency-free analysis with Bioconductor and SAM/BED/BCFtools — no R installation, C toolchain, or containers - Concrete example vignettes, developed fully in the open ## Install ```bash npx -y biomcp doctor # diagnose a machine: Node gate, config health, feature gates, peer deps npx biomcp # zero-config stdio MCP server (this is what MCP clients run); Node >= 22.13 ``` **Setup is guided in [docs/AGENT-INSTALL.md](docs/AGENT-INSTALL.md)** — a one-minute start, copy-paste config entries for Claude Desktop, Claude Code, Codex, and OpenCode (one canonical pinned command covering every feature), `biomcp doctor` as the single troubleshooting entry point, and agent-friendly paths for API keys and optional features. ## Available Tools Full tool schemas (params, enums, defaults) live in [src/server/README.md](src/server/README.md). ### Gene (7) | Tool | Description | |------|-------------| | `gene_search` | Search genes by symbol, name, or keyword with chromosome filter | | `gene_get` | Get detailed gene info by HGNC symbol with optional sections (core, pathways, protein, ontology, go, interactions, expression, protein_atlas, constraint, druggability, dosage_sensitivity, clinical_evidence, disease_associations, diseases, funding). Set `smart=true` to auto-resolve gene aliases (e.g., "HER2" → "ERBB2") | | `gene_diseases` | Get diseases associated with a gene (DisGeNET / OpenTargets) | | `gene_drugs` | Find drugs targeting a gene (OpenTargets) | | `gene_trials` | Find clinical trials for a gene | | `gene_articles` | Find articles about a gene | | `gene_enrich` | Pathway enrichment analysis for a gene list (Reactome) | ### Variant (4) | Tool | Description | |------|-------------| | `variant_search` | Search variants by rsid, HGVS, gene, ClinVar significance, frequency, CADD | | `variant_get` | Get detailed variant info with optional sections (frequency, predictions, clinical; `alphagenome_scores` currently returns an unavailability error pending reimplementation) | | `variant_oncokb` | Get OncoKB cancer variant annotations (requires `ONCOKB_TOKEN`) | | `variant_trials` | Find clinical trials for a variant | ### Drug (3) | Tool | Description | |------|-------------| | `drug_search` | Search drugs by name, mechanism, or keyword | | `drug_get` | Get detailed drug info with optional sections (us_regulatory, eu_regulatory, who_regulatory, safety, targets, indications, adverse_events — FDA FAERS reactions ranked by report count) | | `drug_trials` | Find clinical trials for a drug | ### Disease (4) | Tool | Description | |------|-------------| | `disease_search` | Search diseases by name, phenotype, or keyword | | `disease_get` | Get detailed disease info by ID (DOID, MONDO, OMIM, etc.) with optional sections (gene_associations, phenotypes, pathways) | | `disease_drugs` | Get drugs for a disease (OpenTargets) | | `disease_trials` | Get clinical trials for a disease (ClinicalTrials.gov) | ### Article (2) | Tool | Description | |------|-------------| | `article_search` | Federated literature search across PubMed, EuropePMC, Semantic Scholar, PubTator, and LitSense with optional date range filtering | | `article_get` | Get detailed article info by identifier (PMID, PMCID, or DOI) with optional sections: `oa` (open access / license info), `annotations`, `graph` (citation graph), `citation` (fast/full citation data) | ### Trial (2) | Tool | Description | |------|-------------| | `trial_search` | Search clinical trials by condition, intervention, status, or phase. Cursor-based pagination via `page_token` | | `trial_get` | Get detailed trial info by NCT ID with optional sections (eligibility, locations, outcomes) | ### Utility (2) | Tool | Description | |------|-------------| | `discover` | Free-text concept resolution across all entity types | | `batch_get` | Retrieve multiple entities in parallel | ### Structural Biology (1) | Tool | Description | |------|-------------| | `pdb` | Search PDB structures, get entry metadata with optional sections (polymer entities, ligands, assembly, experiment, citation), and download structure files (mmCIF/PDB) | ### Patents (2) | Tool | Description | |------|-------------| | `patent_search` | Search patents worldwide (US, EP, WO, JP, 100+ authorities) with assignee/inventor/CPC/status/date filters and relevance ranking (`sort_by`). Quote exact multi-word concepts (e.g. "mRNA display"). Foundational prior art is auto-discovered via co-citation mining (`seminal_prior_art`; disable with `seminal: false`). Default backends: USPTO Public Search full-text (US, keyless, relevance-ranked) + EPO OPS (worldwide, keyed); uspto_odp (US bibliographic metadata) and google_patents (best-effort) available via `source` | | `patent_get` | Get patent details by publication number with sections: abstract, claims (US fulltext via USPTO Public Search; EP/WO via EPO OPS), citations (forward + backward), family, classifications | ### GEO (2) | Tool | Description | |------|-------------| | `geo_search` | Search NCBI GEO for functional genomics studies (expression microarrays, RNA-seq, single-cell series) by entry type (GSE/GSM/GPL/GDS) and organism; results carry cross-links (sra_project, bioproject, pubmed_ids) for chaining | | `geo_get` | Get the full SOFT record for a GEO series/sample/platform: summary, organisms, sample preview (≤20), supplementary file URLs, and cross-references; optionally download the first supplementary file | ### SRA (2) | Tool | Description | |------|-------------| | `sra_search` | Search NCBI's Sequence Read Archive for sequencing experiments and runs by free text, accession, or field syntax; returns experiment/study/sample accessions with library strategy and run counts | | `sra_get` | Get full details for an SRA accession: SRR run (instrument, spots, bases, size), SRX experiment (library design), SRP study (experiment list), or SRS sample; ENA/DDBJ accessions rejected with an ENA pointer | ### GenBank (3) | Tool | Description | |------|-------------| | `genbank_search` | Search NCBI nucleotide records (GenBank/RefSeq/INSDC) by plain terms, accession, or field syntax; results include accession.version, definition, length, organism, topology | | `genbank_get` | Fetch a GenBank/RefSeq record as GenBank flat file or FASTA; whole records capped at 2 Mb — larger records require a `seq_start`/`seq_stop` region (up to 10 Mb, reverse-strand via `strand=2`) | | `genbank_genes` | Map a GenBank/RefSeq accession to its NCBI Gene IDs (elink nuccore→gene) for bridging into gene tools | ### GTEx (2) | Tool | Description | |------|-------------| | `gtex_expression` | Get median gene expression across GTEx tissues (Analysis v10, 54 tissue sites, TPM, highest first); accepts HGNC symbol or Ensembl gene ID, with optional single-tissue filter | | `gtex_eqtl` | Get significant cis-eQTL associations for a gene in a specific GTEx tissue (v10): variant_id, p_value, NES, slope, sorted by ascending p-value | ### Ensembl (4) | Tool | Description | |------|-------------| | `ensembl_lookup` | Resolve a gene in Ensembl terms for any of ~356 species: stable ID (+version), symbol, coordinates on the current assembly, canonical transcript; `expand=true` adds transcripts with translation/protein IDs | | `ensembl_homology` | Find orthologues/paralogues across species via Ensembl Compara — target stable IDs, taxonomy level, percent identity, sorted by identity; filter with `target_species`/`target_taxon` | | `ensembl_consequence` | Compute variant consequences on demand via Ensembl VEP for NOVEL variants and non-human species: most severe consequence, per-transcript effects (SIFT/PolyPhen), co-located ClinVar/COSMIC/gnomAD data. Known human variants get deeper pre-computed scores via `variant_get`; prefer HGVS input over rsIDs for precision | | `ensembl_region` | Query genes/transcripts/known variants in a genomic interval (`chr:start-end`) on the current assembly — locus triage | ### R Analysis (4, optional — `ANALYSIS_R=1`) | Tool | Description | |------|-------------| | `analysis_r_deseq2` | Differential expression for RNA-seq counts with Bioconductor DESeq2 (negative binomial, independent filtering, optional LFC shrinkage) in sandboxed WebAssembly R. Inputs: integer count matrix + sample metadata + design formula; output: markdown table of top genes by adjusted p-value with summary (`format="json"`, `include_full=true` for full base64(gzip(TSV)) table) | | `analysis_r_edger` | Differential expression with edgeR — TMM normalization, empirical-Bayes dispersion, quasi-likelihood F-test (`test="qlm"`) or 2-group exact test; same input/outp
Lo que la gente pregunta sobre biomcp-ts
¿Qué es yeyuan98/biomcp-ts?
+
yeyuan98/biomcp-ts es mcp servers para el ecosistema de Claude AI. Democratizing Agentic Access to Bioinformatics and Biopharmaceutical Databases and Analyses with BioMCP-TS. Part of the BioResearcher Agent Suite. Tiene 12 estrellas en GitHub y su última actualización registrada es del 2026-09-14.
¿Cómo se instala biomcp-ts?
+
Puedes instalar biomcp-ts clonando el repositorio (https://github.com/yeyuan98/biomcp-ts) o siguiendo las instrucciones del README en GitHub. ClaudeWave también te ofrece bloques de instalación rápida en esta misma página.
¿Es seguro usar yeyuan98/biomcp-ts?
+
Nuestro agente de seguridad ha analizado yeyuan98/biomcp-ts y le ha asignado un Trust Score de 85/100 (tier: Trusted). Revisa el desglose completo de comprobaciones superadas y flags en esta página.
¿Quién mantiene yeyuan98/biomcp-ts?
+
yeyuan98/biomcp-ts es mantenido por yeyuan98. La última actividad registrada en GitHub es del 2026-09-14, con 0 issues abiertos.
¿Hay alternativas a biomcp-ts?
+
Sí. En ClaudeWave puedes explorar mcp servers similares en /categories/mcp, ordenados por popularidad o actividad reciente.
Despliega biomcp-ts en tu cloud
Lleva este repo a producción en minutos. Cada plataforma genera su propio entorno con variables de entorno editables.
¿Mantienes este repo? Añade un badge a tu README
Pega el badge en tu README de GitHub para mostrar que está auditado por ClaudeWave. Cada badge enlaza de vuelta a esta página y muestra el Trust Score actual.
[](https://claudewave.com/repo/yeyuan98-biomcp-ts)<a href="https://claudewave.com/repo/yeyuan98-biomcp-ts"><img src="https://claudewave.com/api/badge/yeyuan98-biomcp-ts" alt="Featured on ClaudeWave: yeyuan98/biomcp-ts" width="320" height="64" /></a>Más MCP Servers

Fair-code workflow automation platform with native AI capabilities. Combine visual building with custom code, self-host or cloud, 400+ integrations.

User-friendly AI Interface (Supports Ollama, OpenAI API, ...)

An open-source AI agent that brings the power of Gemini directly into your terminal.

Real-time global intelligence dashboard. AI-powered news aggregation, geopolitical monitoring, and infrastructure tracking in a unified situational awareness interface

🕷️ An adaptive Web Scraping framework that handles everything from a single request to a full-scale crawl!

The fastest path to AI-powered full stack observability, even for lean teams.