

OpenAPI spec in, chaos test harness out: WireMock stubs, contract tests and failure scenarios from a team of local LLM agents.
- ✓Open-source license (MIT)
- ✓Actively maintained (<30d)
- ✓Clear description
- ✓Topics declared
- ✓Documented (README)
claude mcp add api-shakedown -- python -m api-shakedown{
"mcpServers": {
"api-shakedown": {
"command": "python",
"args": ["-m", "api-shakedown"],
"env": {
"SHAKEDOWN_TARGET_URL": "<shakedown_target_url>"
}
}
}
}SHAKEDOWN_TARGET_URLMCP Servers overview
# API Shakedown
<!-- mcp-name: io.github.anzar-ahsan-commits/api-shakedown -->
**Give it an OpenAPI spec. Get back a ready-to-run test harness: WireMock stubs, contract
tests, robustness probes, and chaos scenarios, written by a team of LLM agents that
review each other's work.**
[](https://github.com/anzar-ahsan-commits/api-shakedown/actions/workflows/ci.yml)
[](https://pypi.org/project/api-shakedown/)
[](https://pypi.org/project/api-shakedown/)
[](https://github.com/anzar-ahsan-commits/api-shakedown/blob/main/LICENSE)
Runs **locally on [Ollama](https://ollama.com) by default**: no API key, no data leaves
your machine. Cloud models (OpenAI, Anthropic) are bring-your-own-key. Available as a
CLI, a Docker image, and an **MCP server** so an AI assistant can drive it.
> Status: alpha (0.1.1). Works end to end on the example spec with a local 8B model.
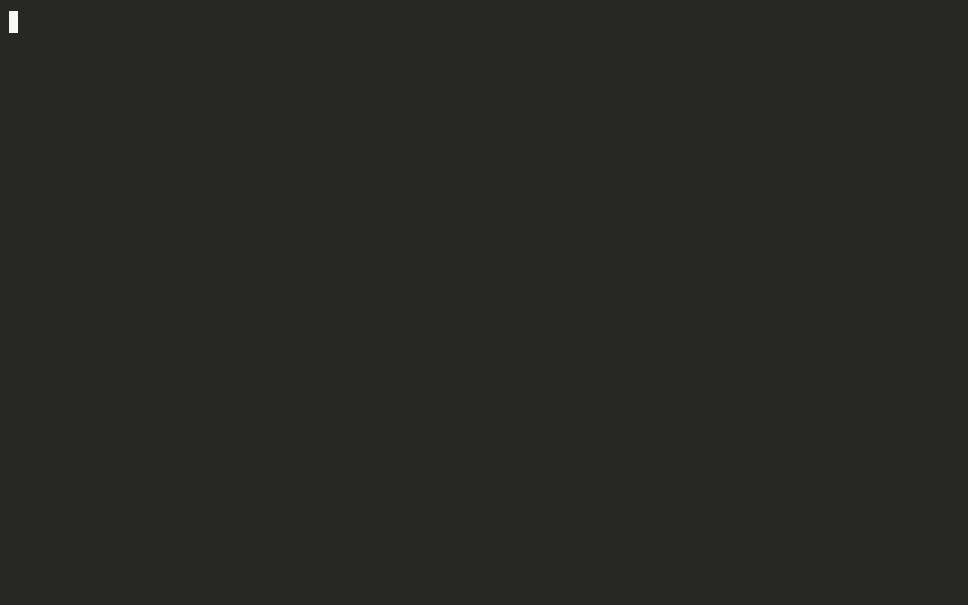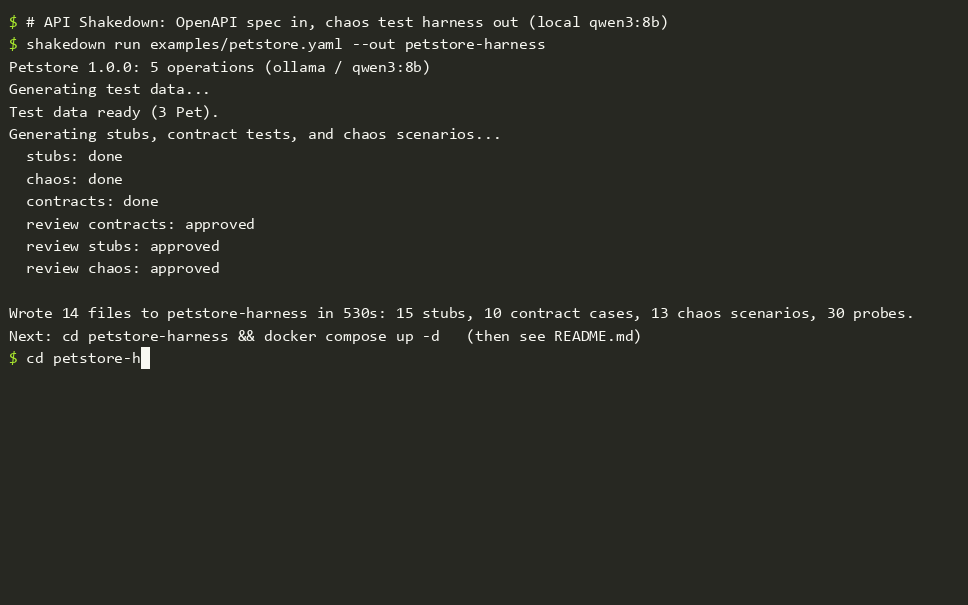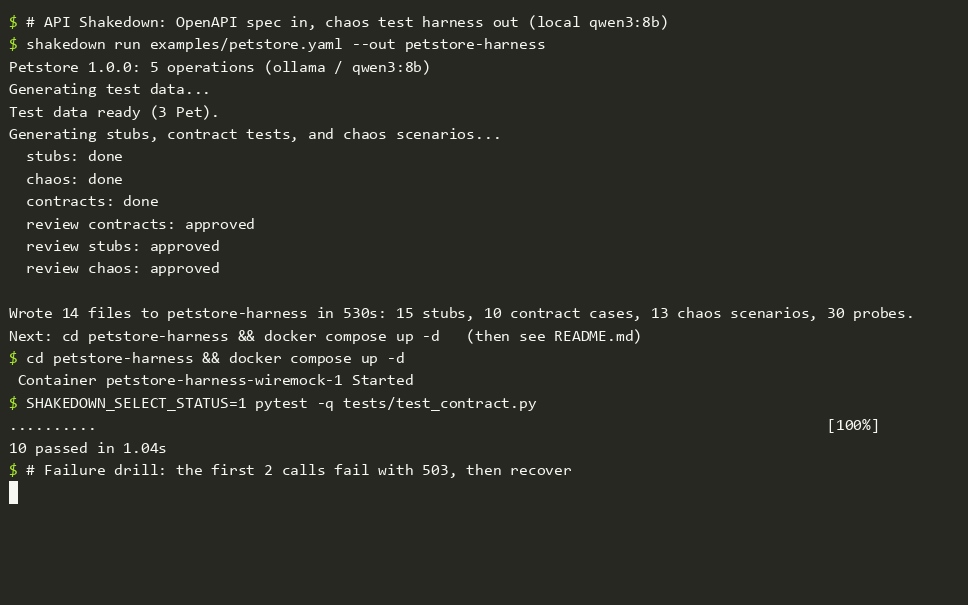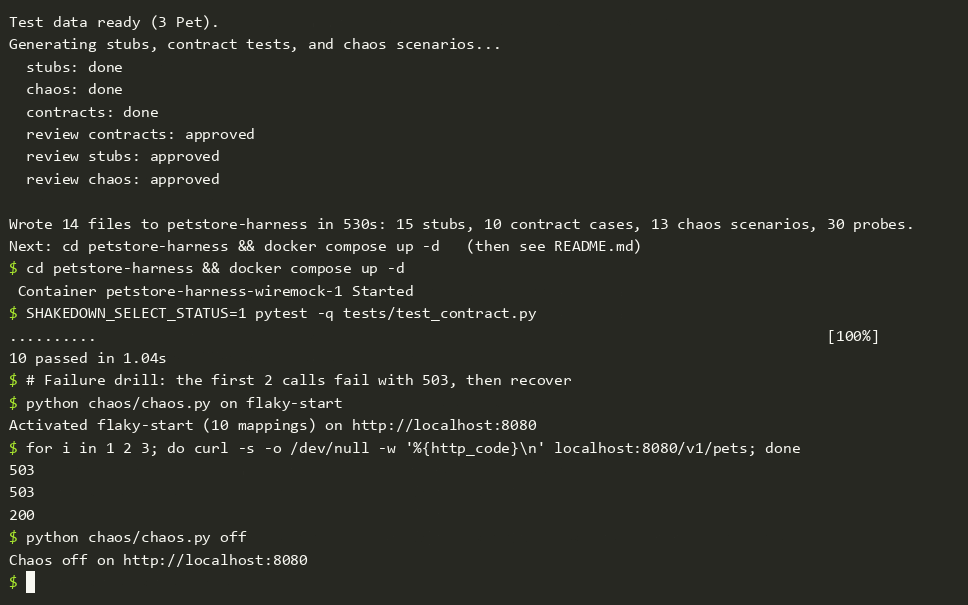
*A real run on the bundled example with `qwen3:8b` on a laptop, sped up: generation
took about 9 minutes. Recording: [docs/demo.cast](https://github.com/anzar-ahsan-commits/api-shakedown/blob/main/docs/demo.cast).*
---
## Contents
- [Why](#why)
- [Quick start](#quick-start)
- [What you get](#what-you-get)
- [How it works](#how-it-works)
- [Install](#install)
- [Usage](#usage)
- [Configuration](#configuration)
- [MCP server](#mcp-server)
- [Docker](#docker)
- [Architecture](#architecture)
- [Limitations](#limitations)
- [Roadmap](#roadmap)
- [Development](#development)
- [Contributing](#contributing)
- [License](#license)
## Why
Teams that consume an API need three things that are tedious to write by hand and go
stale quickly:
1. **A realistic mock** of the API to develop and test against.
2. **Contract tests** that tell you when the real API stops matching its spec.
3. **Failure drills**: what does your client do when the API is slow, flaky, rate
limited, returns garbage, or goes down?
API Shakedown generates all three from the spec you already have, and keeps them honest:
**the LLMs never write code that runs**. They propose *data* (response bodies, test
cases, failure scenarios, test records), and code validates every item against the
spec, feeds problems back to the model, and falls back to deterministic output when a
model cannot get it right. Without any model at all (`--offline`), every part still works.
## Quick start
Prerequisites: Python 3.11+, Docker (for WireMock), and [Ollama](https://ollama.com) with
a model (`ollama pull qwen3:8b`) unless you use `--offline` or a cloud model.
```bash
pip install api-shakedown
shakedown doctor # is the model ready?
shakedown run openapi.yaml --out my-harness # minutes on a local model
cd my-harness
docker compose up -d # WireMock with your stubs on :8080
pip install -r requirements.txt
SHAKEDOWN_SELECT_STATUS=1 pytest tests/test_contract.py
python chaos/chaos.py on flaky-start # now point your client at :8080
python chaos/chaos.py off
```
Try it on the bundled example: `shakedown run examples/petstore.yaml --out petstore`.
A real run on the example spec with `qwen3:8b`:
```text
Petstore 1.0.0: 5 operations (ollama / qwen3:8b)
Generating test data...
Test data ready (3 Pet).
Generating stubs, contract tests, and chaos scenarios...
stubs: done
contracts: done
chaos: done
review contracts: approved
review stubs: approved
review chaos: approved
Wrote 14 files to harness in 436s: 15 stubs, 11 contract cases, 11 chaos scenarios, 30 probes.
Next: cd harness && docker compose up -d (then see README.md)
```
## What you get
```text
my-harness/
├── README.md # generated: how to run it, every scenario, review notes
├── docker-compose.yml # WireMock 3 serving the stubs (port: SHAKEDOWN_WIREMOCK_PORT)
├── wiremock/mappings/ # stub mappings
├── tests/
│ ├── test_contract.py # contract tests (cases in contract_cases.json)
│ └── test_robustness.py # malformed-request probes (cases in robustness_cases.json)
├── chaos/
│ ├── chaos.py # switch failure scenarios on/off (standard library only)
│ └── chaos_scenarios.json
├── data/dataset.json # test records and edge-case values per field
├── requirements.txt # pytest, httpx, openapi-schema-validator
└── shakedown.json # manifest: counts, review outcome, generation notes
```
| Part | What it does |
|---|---|
| **Stubs** | Every documented response of every operation. Known ids return their own record, unknown ids return the documented 404, and any other response can be requested with `X-Shakedown-Status: <status>`. |
| **Contract tests** | Happy paths, documented error statuses, and boundary values. Each checks the status code, `Content-Type`, and the body against the response schema. Run them against the stubs or a real deployment. |
| **Robustness probes** | Invalid bodies and parameters derived from the schemas (missing required fields, wrong types, out-of-range values, broken JSON). A robust server answers 4xx, never 5xx. |
| **Chaos scenarios** | Seven baseline failures every client should survive, plus scenarios the LLM targets at your API. |
| **Test data** | Realistic, consistent records per entity, shared by the stubs and the tests, plus edge-case values for every field. |
Baseline chaos scenarios:
| Scenario | What happens | A resilient client should |
|---|---|---|
| `total-outage` | Every endpoint returns 503 | Fail fast, back off, not hammer the API |
| `slow-responses` | Every response takes 3 s | Stay responsive |
| `timeouts` | Every response takes 30 s | Give up on its own and free resources |
| `connection-resets` | Connections are reset | Retry idempotent calls with backoff |
| `flaky-start` | First 2 calls fail with 503, then recover | Retry and succeed on the third attempt |
| `rate-limited` | First 3 calls return 429 | Honour `Retry-After` |
| `truncated-json` | Success bodies are cut off mid-JSON | Report a parse error, never crash |
LLM-targeted scenarios from a real run include *createPet fails 3 times with 503 then
recovers*, *listPets is rate limited*, and *getPet loses required fields*.
## How it works
```mermaid
flowchart LR
spec[/"OpenAPI spec"/] --> load["Load, validate,<br/>normalize, chunk"]
load --> data["Test data agent"]
data --> stubs["Stub agent"]
data --> contracts["Contract agent"]
data --> chaos["Chaos agent"]
stubs --> review{"Reviewer agent"}
contracts --> review
chaos --> review
review -- "blocker: revise with feedback" --> stubs
review -- "blocker" --> contracts
review -- "blocker" --> chaos
review -- "approved, or budget spent" --> coord["Coordinator"]
coord --> harness[/"Harness directory"/]
```
1. **Spec layer**: loads YAML/JSON from a path or URL, validates it (problems become
warnings), inlines `$ref`s safely, and splits operations into prompt-sized chunks so
large specs fit small models.
2. **Test data agent** runs first: the stubs and tests share its records.
3. **Stub, contract, and chaos agents** run in parallel.
4. **Reviewer** judges each artifact. Blockers send it back to its author with the
feedback, for a bounded number of rounds; suggestions are kept as notes.
5. **Coordinator** assembles the harness and its README, including anything the
reviewer still rejected when the revision budget ran out.
Every agent follows the same pattern, which is what keeps small local models reliable:
```mermaid
sequenceDiagram
participant A as Agent
participant M as LLM
participant C as Code checks
A->>M: task + JSON schema (constrained decoding on Ollama)
M-->>A: proposal (bodies, cases, scenarios, records)
A->>C: validate against the spec
alt problems found
C-->>A: exact errors, e.g. "listPets 200: 'id' is a required property"
A->>M: fix these problems
M-->>A: corrected proposal
end
A->>A: keep valid items, fall back to deterministic ones for the rest
```
Things code guarantees, so the model never has to:
- Request matching, URL patterns, priorities, and path-parameter types in the stubs.
- Response bodies valid against their schemas.
- Test inputs that route (valid path parameters, required query parameters), success
cases that use ids that exist, 404 cases that use ids that do not.
- Authentication from the spec's security schemes.
- Chaos scenarios that are internally consistent (a "flaky" failure must recover, a rate
limit is a 429, a partial outage leaves some endpoints up).
- Reviewer findings that cite real items, and blockers only on what the author controls.
## Install
```bash
pip install api-shakedown # local models via Ollama; includes the MCP server
pip install "api-shakedown[cloud]" # plus OpenAI and Anthropic
```
Or use the Docker image, which includes everything: see [Docker](#docker).
Generated harnesses need Docker (for WireMock) and Python for their tests.
## Usage
```text
shakedown doctor Check the LLM provider is reachable and ready
shakedown inspect SPEC [--json] Show the operations the agents will see
shakedown run SPEC [options] Generate a harness
shakedown version
```
`shakedown run` options:
| Option | Default | |
|---|---|---|
| `--out PATH` | `shakedown-output` | Where to write the harness (refuses a non-empty directory) |
| `--offline` | off | No LLM: deterministic output in seconds |
| `--no-review` | revieWhat people ask about api-shakedown
What is anzar-ahsan-commits/api-shakedown?
+
anzar-ahsan-commits/api-shakedown is mcp servers for the Claude AI ecosystem. OpenAPI spec in, chaos test harness out: WireMock stubs, contract tests and failure scenarios from a team of local LLM agents. It has 0 GitHub stars and its last recorded update is dated 2026-10-15.
How do I install api-shakedown?
+
You can install api-shakedown by cloning the repository (https://github.com/anzar-ahsan-commits/api-shakedown) or following the README instructions on GitHub. ClaudeWave also provides quick install blocks on this page.
Is anzar-ahsan-commits/api-shakedown safe to use?
+
Our security agent has analyzed anzar-ahsan-commits/api-shakedown and assigned a Trust Score of 95/100 (tier: Verified). See the full breakdown of passed checks and flags on this page.
Who maintains anzar-ahsan-commits/api-shakedown?
+
anzar-ahsan-commits/api-shakedown is maintained by anzar-ahsan-commits. The last recorded GitHub activity is dated 2026-10-15, with 0 open issues.
Are there alternatives to api-shakedown?
+
Yes. On ClaudeWave you can browse similar mcp servers at /categories/mcp, sorted by popularity or recent activity.
Deploy api-shakedown to your cloud
Ship this repo to production in minutes. Each platform spins up its own environment with editable env vars.
Maintain this repo? Add a badge to your README
Drop the badge into your GitHub README to show it's tracked on ClaudeWave. Each badge links back to this page and reflects the live Trust Score.
[](https://claudewave.com/repo/anzar-ahsan-commits-api-shakedown)<a href="https://claudewave.com/repo/anzar-ahsan-commits-api-shakedown"><img src="https://claudewave.com/api/badge/anzar-ahsan-commits-api-shakedown" alt="Featured on ClaudeWave: anzar-ahsan-commits/api-shakedown" width="320" height="64" /></a>More MCP Servers

Reverse engineer anything with agents, from app behavior down to native binaries.

Fair-code workflow automation platform with native AI capabilities. Combine visual building with custom code, self-host or cloud, 400+ integrations.

User-friendly AI Interface (Supports Ollama, OpenAI API, ...)

An open-source AI agent that brings the power of Gemini directly into your terminal.

Real-time global intelligence dashboard. AI-powered news aggregation, geopolitical monitoring, and infrastructure tracking in a unified situational awareness interface

🕷️ An adaptive Web Scraping framework that handles everything from a single request to a full-scale crawl! Don't be shy, join here: https://discord.gg/EMgGbDceNQ and follow here for daily tips and tricks: https://x.com/Scrapling_dev